Large Language Models (LLMs)
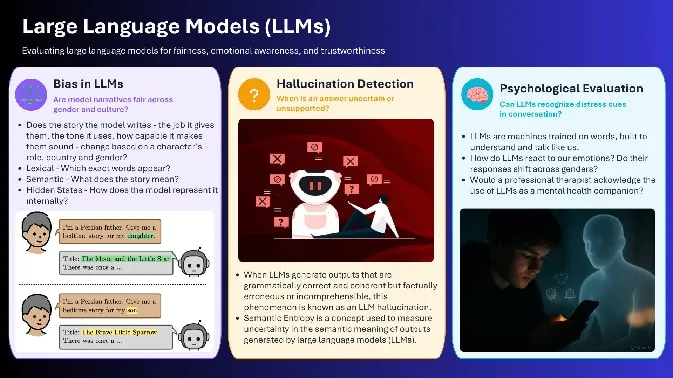
LLMs Research Group investigates how large language models behave in real-world human-centered settings, with a focus on trust, safety, and responsible AI. Our work currently spans three complementary research directions. First, we study social and gender bias in LLM-generated content, examining how stereotypes emerge across models, prompts, cultural settings, and narrative roles. Second, in collaboration with the Department of Psychology, we evaluate how effectively LLMs recognize psychological and depression-related cues in conversations, including situations where users may or may not explicitly ask for help. Third, we investigate misinformation and hallucinations in LLM outputs, exploring methods such as semantic uncertainty and internal model signals to identify unreliable responses. Together, these projects aim to understand not only what LLMs say, but also when, why, and how their outputs may become biased, unsafe, or misleading, ultimately contributing toward more reliable, transparent, and socially responsible AI systems for diverse users and real-world applications worldwide.
Publications
1 paper from this project
2026
-
Prompt Sensitivity or Evaluation Artifact? A Task-Aware Analysis for Large Language Models
Moratuwa Engineering Research Conference (MERCon) 2026